The proposition: Are APAC enterprises overspending on algorithms while neglecting workflows, governance, and handoffs that determine real business impact?
For the past two years, enterprise AI strategy in the Asia Pacific region has often boiled down to a single question: Which model should a firm back? Boardrooms have approved seven- and eight-figure budgets for frontier foundation models, agentic frameworks, and enterprise AI licenses on a simple assumption: secure the best algorithmic horsepower, and commercial transformation will follow.
Early deployments tell a different story. Across industries, organizations are spending aggressively on machine intelligence while productivity gains fall short of expectations. In many cases, the binding constraint is not model capability or compute, but organizational architecture: the workflows, handoff protocols, data pipelines, and governance that determine whether AI output becomes business outcome.
Early deployments tell a different story. Across industries, organizations are spending aggressively on machine intelligence while productivity gains fall short of expectations. In many cases, the binding constraint is not model capability or compute, but organizational architecture: the workflows, handoff protocols, data pipelines, and governance that determine whether AI output becomes business outcome.
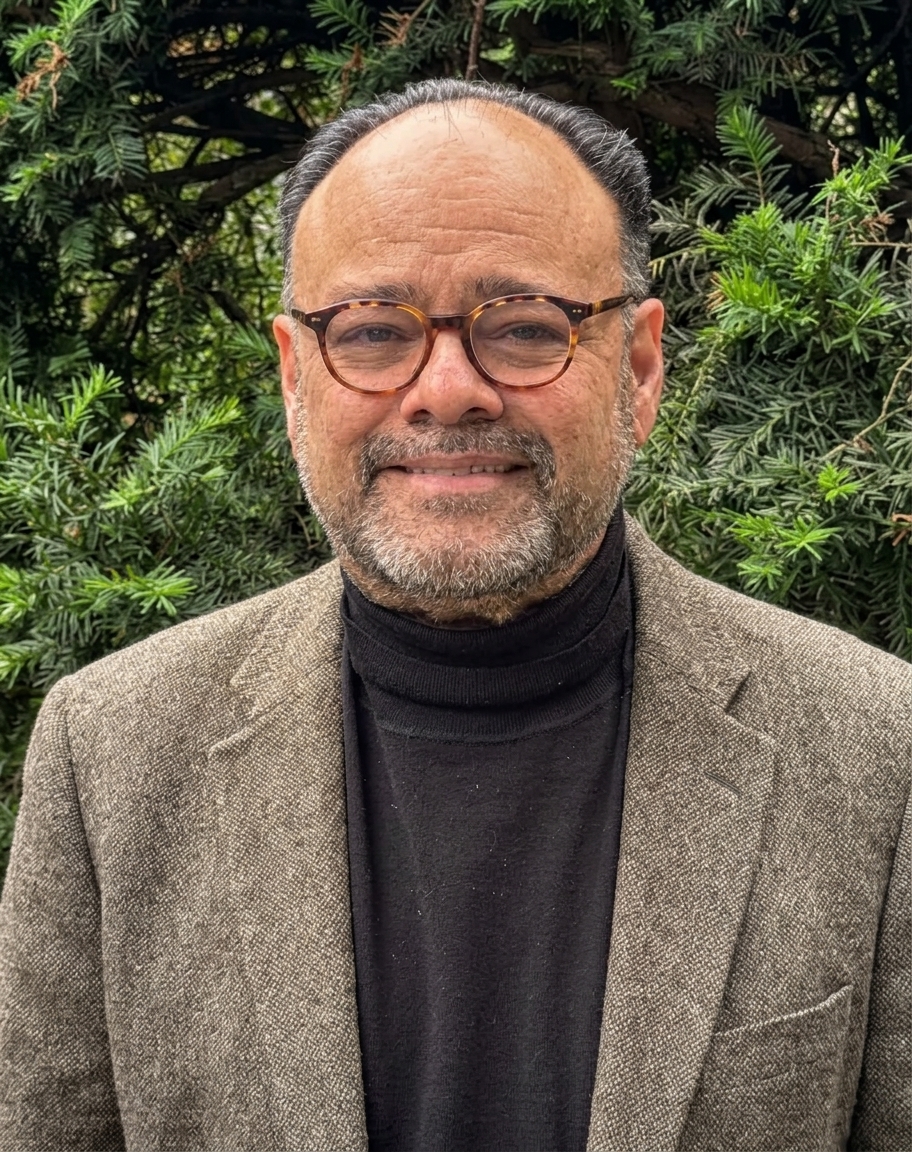
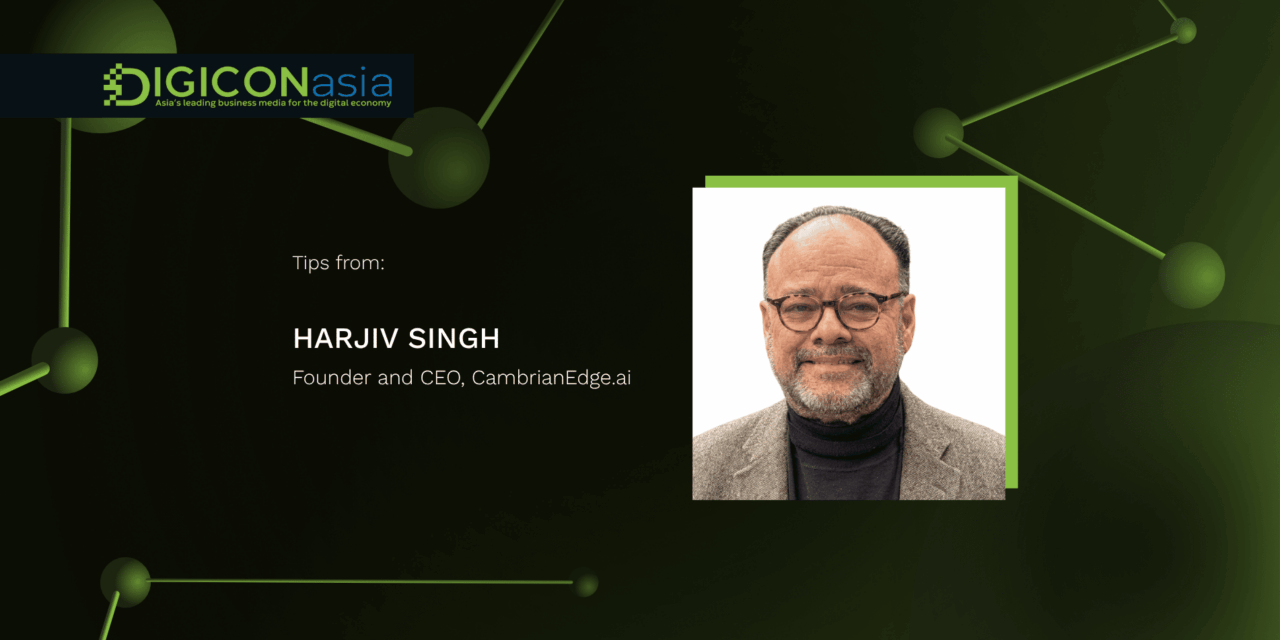
Harjiv Singh, founder and CEO, CambrianEdge.ai
It is within this context that Harjiv Singh, founder and CEO, CambrianEdge.ai, advances a blunt thesis: the “AI arms race” over frontier models is for amateurs. The companies that will win over the next five years, he argues, are not those that rent the largest models, but those that “fix the baton pass” – redesigning the handoffs, governance, and operating models that turn AI output into business outcome.
Singh opined to DigiconAsia.net: “Organizations are spending aggressively on machine intelligence while watching productivity flatline. The primary barrier to enterprise AI transformation has never been model capability, benchmark performance, or computational power. The barrier is organizational architecture.”
His prescription is equally clear: shift investment away from vendor selection and into a “model-agnostic operating layer” that decouples business logic and governance from any single model API, treats models as interchangeable utilities, and enforces transparent human-machine workflows.
That thesis is provocative, but it also raises uncomfortable questions for CIOs and transformation leads: Is model choice really secondary? How much of the problem is truly architectural? And what does the evidence from early enterprise deployments actually show?
Examining the 10–20–70 pattern
Singh’s argument leans heavily on Boston Consulting Group’s (BCG) 10–20–70 transformation framework, where algorithms account for roughly 10% of the AI transformation challenge; technology and data infrastructure 20%; and around 70% hinges on changing people, processes, and operating models.
BCG itself frames this as a rule of thumb for leaders, not a universal constant. In its published guidance, the firm emphasizes that the exact split varies by use case and industry, and that successful transformations require strategic alignment from the top, workforce redesign, and new ways of working, not just new models.
Still, the pattern Singh highlights is real: in many enterprises, the bulk of budget and executive attention flows into the 10% algorithmic layer — model licenses, pilots, and proofs-of-concept — while workflow redesign, change management, and governance lag.
Early evidence: productivity gains are uneven
Singh’s claim that “productivity flatlines” despite heavy AI spend is stronger as a narrative than as a settled fact. Macro-level evidence remains mixed:
- Some studies and internal pilots show significant time savings on specific tasks (coding, drafting, customer support triage), but these do not always translate into measured productivity at the team or firm level.
- Other analyses point to implementation friction: integration work, retraining, and new coordination overhead that can offset task-level gains in the short term.
- Regional data for APAC is particularly thin; most public surveys are global and dominated by North American and European respondents.
For example, in a 2025 BCG survey of more than 4,500 employees across nine APAC markets, 78% had reported using AI at work at least weekly, but only 57% said their companies were redesigning workflows to integrate it effectively. In other words, Singh’s diagnosis — that many organizations are under-delivering relative to AI spend — is plausible, but the “flatline” framing risks overstating the case.
A more precise theory would be: productivity gains are uneven, often concentrated in narrow tasks, and frequently fail to scale without workflow redesign.
Three structural traps
Singh identifies three architectural traps that stall AI programmes: the handoff deficit, the fragmented tool stack, and the literacy trap. Each maps closely to patterns that architects and transformation leads describe in interviews.
1. The handoff deficit
Legacy operations assume human-to-human delegation, where shared context and tribal knowledge fill in operational blanks. AI systems and digital agents possess no such intuition. Without explicit, structured protocols for handing work between humans and machines, teams spend significant time reconciling contradictory outputs, re-running prompts, and fixing invisible errors. In practice, this shows up as:
- Unclear ownership of AI-generated drafts and decisions
- Manual “quality gates” that reintroduce latency
- Rework loops between business, legal, compliance, and IT
For example, at a major APAC bank, an AI system now drafts small-business loan memos in minutes. However, each output still passes through three manual review stages: front-office validation, credit risk sign-off, and compliance check — because regulators and internal auditors require documented human accountability for every credit decision. The net time saving per file is often marginal, while staff report additional cognitive load reconciling model drafts with legacy checklists.
2. The fragmented tool stack
Point solutions multiply quickly. Marketing adopts one proprietary model, finance contracts another, and regional operations deploys a third. Because these systems share neither context nor canvas, human workers become expensive middleware, manually copy-pasting data across disconnected browser tabs and re-entering context for each tool.
The result is not just inefficiency; it is increased risk. Data lineage becomes opaque, audit trails fragment, and governance policies are enforced inconsistently across tools.
This is where Singh’s proposed remedy – a model-agnostic operating layer – is most attractive in theory. An orchestration or middleware layer that abstracts multiple model APIs, enforces common logging and governance, and provides a unified workspace could, in principle, reduce context switching and integration debt.
But architects caution that this can simply shift the problem. “You can end up with lock-in at the orchestration layer instead of the model layer,” says [insert independent architect/CIO quote]. “Now you’re dependent on one vendor’s roadmap for routing, evaluation, and observability.”
3. The literacy trap
Basic AI literacy teaches an employee how to type an effective prompt. True organizational fluency requires teaching teams how to interrogate machine logic, evaluate data provenance, and govern joint human-machine workflows. Training that stops at prompt mechanics leaves the enterprise vulnerable to blind algorithmic drift, over-reliance on single vendors, and unexamined failure modes. Here, Singh’s argument aligns with a broader shift in training priorities. Several multinationals operating in APAC are moving from “prompt engineering” courses to curricula that cover evaluation frameworks, risk scenarios, and workflow design.
For example, in Singapore, several multinationals have built internal “AI fluency” programmes aligned with the national Model AI Governance Framework, training staff not only in prompt techniques but also in data provenance, risk materiality assessment, and human-in-the-loop design.
Architecture options, not single blueprints
Singh’s preferred solution — a model-agnostic collaboration layer — is one architectural pattern among several. In practice, organizations are experimenting with:
- Orchestration and routing layers that abstract multiple model APIs, enforce common logging and governance, and route tasks by cost, latency, and capability.
- Workflow-native AI, where models are embedded directly into core business systems (ERP, CRM, ticketing, content management) with explicit handoff states and approval steps.
- Platform consolidation, where enterprises deliberately limit the number of AI tools and standardize on a smaller set of integrated platforms to reduce context switching and integration debt.
- Governance-first approaches, where model choice is secondary to establishing evaluation frameworks, red-teaming processes, and clear risk ownership.
Each pattern carries trade-offs. Orchestration layers can introduce new lock-in at the platform level, add latency, and complicate observability. Workflow-native AI requires deep integration work and may constrain model flexibility. Platform consolidation can reduce best-of-breed options. Governance-first approaches can slow deployment if not paired with clear delivery mandates.
Where model choice still matters
Singh’s framing — “the primary barrier… has never been model capability” — is useful as a corrective to model fetishism, but it risks swinging the pendulum too far. In several scenarios, model choice remains critical:
- Regulated domains (financial services, healthcare, public sector), where model behavior, auditability, and data residency constraints can rule out certain providers or deployment modes.
- Latency-sensitive applications, where on-device or regional models outperform distant frontier APIs.
- Domain-specific tasks, where specialised models outperform general-purpose systems on narrow benchmarks (e.g. medical imaging, code generation for specific stacks, scientific text).
- Cost and sovereignty considerations, where local or open-weight models offer better total cost of ownership or align with data-sovereignty policies.
Architecture and model choice are interlocking decisions, not opposites. A well-designed operating model can amplify a mediocre model’s usefulness; a poor architecture can waste even the best model. But in some use cases, the model itself is the binding constraint.
Implications for APAC leaders
For C-suite executives and board directors across Asia Pacific, several implications follow from stress-testing Singh’s thesis:
- Treat AI as an operating-model programme, not a procurement exercise. Budgets and steering committees should reflect the 70% people-and-process reality, not just model licenses.
- Design for handoffs first. Map critical workflows end-to-end, define explicit human-machine handoff points, and instrument them for visibility and audit.
- Measure throughput, not just output. Track cycle time, rework rates, and decision latency, not just the volume of AI-generated content.
- Plan for multi-model reality. Assume you will use multiple models over time; design data, governance, and integration layers accordingly.
- Invest in fluency, not just literacy. Move beyond prompt training to curricula on data provenance, evaluation, and joint human-machine workflow design.
Singh’s core insight — that the next phase of enterprise AI advantage will be determined by handoffs, not just horsepower — is a useful corrective to the current model arms race. But the evidence suggests a more nuanced playbook: architecture matters enormously, yet model choice, deployment mode, and vendor strategy still shape risk, cost, and performance in critical ways.
The sweet spot would be for an enterprise to hold both truths at once: design robust, human-led operating models, while making disciplined, evidence-based bets on the models that power them.